
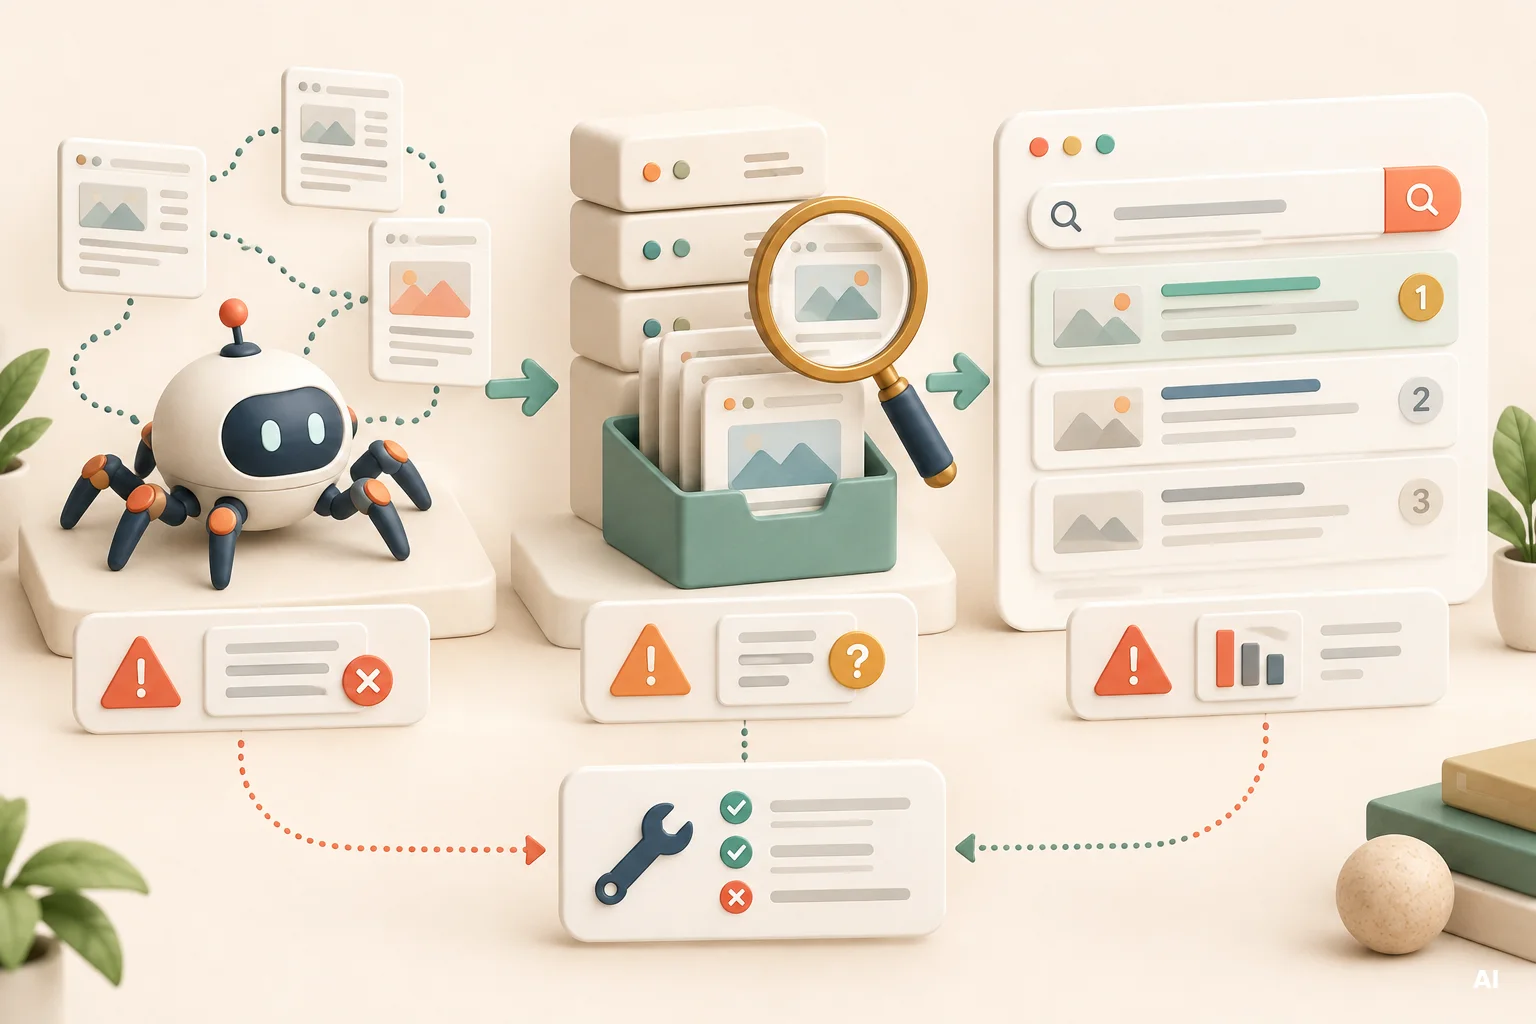
Search engines help people discover useful information across billions of web pages, but their work involves more than simply matching a query with repeated keywords. To understand how search engines work, it helps to separate the process into three main stages: crawling, indexing, and ranking. A page can succeed at one stage and encounter problems at the next, which is why visibility requires both accessible technology and relevant, useful content. If you are new to the wider topic, begin with this beginner’s guide to search engine optimization.
What Does a Search Engine Do?
A search engine organizes information so that it can respond to a user’s query with relevant results. Automated programs discover accessible URLs, retrieve their content, analyze what each page contains, and store eligible information in a searchable index. When someone searches, ranking systems evaluate potential matches and determine which results to present.
Although the process is often summarized as crawling, indexing, and ranking, these are separate activities. Crawling means discovering and accessing a resource. Indexing involves analyzing and storing information about it. Ranking happens when the search engine selects and orders indexed resources for a particular query. Discovery does not guarantee indexing, while indexing does not guarantee prominent visibility in search engine results.
Step 1: How Search Engines Crawl the Web
Search engine crawling is the process of finding URLs and requesting their content with automated software commonly called crawlers, spiders, or bots. Search engines do not have a single directory containing every page on the web, so they must continually discover new and updated URLs.
How crawlers discover URLs
A crawler can find a page by following a link from a page it already knows, processing a submitted sitemap, or revisiting a URL discovered during an earlier crawl. Links are particularly important because they provide paths between resources. Google states that many new pages are discovered through links rather than through manual submission.
A new page that is not included in navigation, linked from another accessible page, or listed in a sitemap may be difficult to discover. Such an isolated URL is sometimes described as an orphan page. A logical structure reduces this risk by giving crawlers clear routes from the home page and category pages to more detailed content.
What happens when a crawler visits a page?
After discovering a URL, the crawler requests it from the website’s server. The response may contain HTML, images, scripts, videos, and other resources needed to understand or render the page. Server errors, login requirements, broken redirects, or inaccessible resources can prevent the crawler from retrieving everything it needs.
Website owners can influence crawler access through mechanisms such as robots.txt. However, blocking a URL from crawling is not the same as explicitly preventing indexing. If the objective is to keep an accessible page out of compatible search indexes, a correctly implemented noindex directive is generally the relevant control. The crawler must be able to access the page to detect that directive.
Step 2: How Search Engines Index Pages
Once a page has been crawled, a search engine may analyze its text, images, videos, headings, links, metadata, and other signals. Search engine indexing is the stage in which eligible information is processed and stored in the search engine’s index. An indexed page can potentially appear in results, but inclusion is not automatic or guaranteed.
Understanding a page’s content and purpose
During indexing, systems attempt to determine the page’s subject, language, format, and relationship to other resources. Clear headings, descriptive page titles, useful main content, understandable links, and accessible supporting media can make that interpretation easier. Search engines may also process structured information and signals that identify important page elements.
This does not mean that a page should repeat one phrase excessively. Search systems can evaluate concepts and relationships between words rather than relying only on exact-match keywords. The practical goal is to cover the subject clearly enough that both visitors and search engines can understand what need the page addresses.
Duplicate pages and canonical selection
Websites sometimes make substantially similar content available under several URLs. This can happen because of tracking parameters, filters, product variations, or alternative URL paths. Search engines may group duplicate or near-duplicate resources and select one URL as the canonical version. As a result, a crawled URL may not be indexed separately even though its content has been processed.
Canonical annotations can communicate a preferred version, but they are signals rather than a way to force every URL into the index. Consistent internal links, sitemap entries, redirects, and canonical annotations help reinforce which URL should represent the content.
Step 3: How Search Engines Rank Results
Ranking occurs when a person submits a query. The search engine searches its index for matching resources and uses automated systems to decide which results are likely to be the most relevant and useful. This is the essential answer to questions about how Google ranks pages: it uses many systems and signals rather than one universal score or checklist.
Relevance, meaning, and usefulness
Ranking systems attempt to understand what the query means, which indexed pages address that meaning, and which options may provide a satisfying answer. The wording of the query matters, but so do related concepts, content quality, page purpose, and context. Depending on the search, factors such as language, location, device, and freshness may influence which results are presented.
Links can contribute to this evaluation by helping systems understand relationships between pages and identify potentially useful resources. However, links are only part of a much broader process. A page does not rank merely because it has the highest number of backlinks, uses a keyword a specific number of times, or belongs to a website with a matching domain name.
Why rankings differ between queries
The same page can rank well for one query and poorly for another because ranking is query-dependent. A detailed guide may be appropriate for an informational search, while a product or service page may better satisfy a transactional search. Search result features can also change with the query, meaning users may see standard listings, images, videos, local results, or other formats.
What Is the Difference Between Crawling and Indexing?
Crawling asks, “Can the search engine find and access this URL?” Indexing asks, “Can the search engine process this resource and store it as an eligible result?” A successful crawl is therefore not proof that the page has been indexed.
For example, a crawler may visit a page and discover a noindex directive, recognize it as a duplicate of another URL, or determine that there is insufficient reason to store it separately. Conversely, information about a URL can occasionally appear in an index even when the crawler was unable to access its full content, particularly when the URL is known through external references.
The distinction matters when diagnosing visibility. If a URL has not been discovered, improve links and discovery signals. If it cannot be crawled, investigate access and server responses. If it was crawled but not indexed, review directives, duplication, canonical selection, and content value. If it is indexed but not visible for an important query, examine relevance, intent, quality, and competition.
Why a Page May Not Appear in Search Results
A missing result is not always a ranking problem. The page may have failed at discovery, crawling, or indexing before ranking was even considered. Alternatively, it may be indexed but not judged relevant enough for the query being tested. Google’s own inspection documentation emphasizes that an indexed URL is eligible to appear but is not guaranteed to be displayed for every search.
Common reasons include an unlinked URL, crawler restrictions, a noindex directive, server errors, redirect problems, duplicate content, unexpected canonical selection, inaccessible resources, or content that does not provide sufficient value. A recently published or updated page may also require time to be discovered and processed. Sitemaps and indexing requests can support discovery, but neither guarantees inclusion.
When investigating a missing page, work through the stages in order rather than changing titles or adding keywords immediately. A practical diagnostic sequence is provided below.
- Confirm that the URL works: Open it without being logged in and check that it loads the intended content.
- Check crawler access: Review robots.txt, server responses, redirects, and any authentication requirements.
- Check indexing instructions: Look for noindex directives and verify that the canonical URL is appropriate.
- Inspect discovery signals: Confirm that an accessible page links to the URL and that the correct URL appears in the sitemap when appropriate.
- Review the page’s value: Make sure it offers distinct, useful content rather than duplicating another page.
- Evaluate query relevance: Compare the page’s purpose and format with the apparent intent behind the target search.
How Links and Site Structure Help Discovery
Internal links connect pages within the same website. They allow visitors to navigate between related resources and give crawlers paths to follow. Descriptive anchor text also provides context about the destination before either a person or a search engine opens it.
A logical structure usually moves from broad pages to more specific ones. For example, a store might connect its home page to major categories, categories to subcategories, and subcategories to relevant product pages. Supporting guides can then link to suitable categories or related educational content. This hierarchy helps indicate which pages are important and how different topics or offers relate to one another.
Important pages should not depend entirely on an internal search box or on links generated only after complicated interactions. They should be reachable through standard, crawlable links wherever practical. Sitemaps can provide an additional discovery signal, but they should support rather than replace usable navigation and internal linking.
How Search Intent Influences Ranking
Search intent is the goal behind a query. A person might want to learn how something works, reach a particular website, compare available options, find a nearby business, or complete a purchase. A page is more likely to compete effectively when its purpose and format correspond to that underlying need.
SEO professionals often describe intent using practical labels such as informational, navigational, commercial, and transactional. These labels are useful for planning, but real searches can contain more than one need. Someone searching for a product category may want to compare choices and make a purchase during the same visit.
Intent also explains why adding more keywords may not improve a page’s position. If search engine results primarily contain tutorials, a short sales page may not provide the answer users expect. If results mainly contain product or category pages, a general article may be too far removed from the desired action. A structured process for evaluating these differences is covered in the guide to keyword research and search intent.
Ranking systems are designed to identify relevant and helpful results, so content should address the visitor’s actual question instead of merely imitating phrases found on competing pages. Clear scope, useful detail, accurate information, and a satisfying main content experience provide a stronger foundation than keyword repetition.
How to Check Whether Search Engines Can Find Your Pages
Website owners should combine direct checks with information from official webmaster tools. For Google visibility, the URL Inspection tool in Search Console can show what Google knows about a specific URL, whether it was crawled, whether it is indexed, and which canonical version was selected. Its live test can also help identify current access or indexability problems.
A reliable review should examine each stage separately. The following process keeps the investigation focused.
- Inspect the exact URL: Enter the complete address into the search engine’s webmaster tool rather than checking only the domain.
- Compare indexed and live information: The stored version may differ from the page currently available on the website.
- Review discovery details: Check whether the URL was found through a sitemap or another page.
- Review crawl details: Look for blocked access, failed responses, redirect errors, or resource-loading problems.
- Review indexing details: Confirm the indexing status and compare the declared canonical with the search engine’s selected version.
- Check search performance: If the URL is indexed, examine whether it receives impressions for relevant queries before assuming it is completely invisible.
- Request indexing when appropriate: After publishing or correcting an important URL, an indexing request may prompt another review, although inclusion is not guaranteed.
For a broader review of access, directives, mobile usability, performance, security, sitemaps, and canonicalization, use a prioritized technical SEO checklist. Fix issues that prevent important pages from being accessed or indexed before spending time on minor technical warnings.
Frequently Asked Questions About Search Engines
Can a page be crawled but not indexed?
Yes. Crawling means the search engine accessed the URL, while indexing means it processed and stored the page as an eligible result. A crawled page may remain unindexed because of a noindex directive, duplication, canonical selection, quality concerns, or another eligibility issue.
Can an indexed page fail to appear in search results?
Yes. Indexing makes a page eligible to appear, but it does not guarantee visibility for a particular query. The page may not be sufficiently relevant or competitive, and other conditions can affect whether it is served in the results.
Does submitting a sitemap guarantee indexing?
No. A sitemap helps a search engine discover new or updated URLs, but it is not a command to crawl or index every listed page. URLs in the sitemap should be accessible, canonical, and suitable for search visibility.
Can search engines find a page without a sitemap?
Yes. Crawlers can discover pages by following links from known resources. A sitemap is particularly helpful for large, new, frequently updated, or complex websites, but crawlable internal links remain essential.
Does robots.txt remove a page from the index?
Not necessarily. Robots.txt primarily controls crawling. A blocked URL may still be known through links or other signals. To prevent an accessible page from being indexed by search engines that support the instruction, use an appropriate noindex directive and allow the crawler to access the page so it can read that directive.
How long does crawling and indexing take?
There is no fixed timeline. Processing can depend on the website, the page, server availability, internal links, update patterns, and other factors. An indexing request or sitemap can communicate that a URL exists or has changed, but neither provides an immediate result or a guarantee of inclusion.
Can a website owner pay for higher organic rankings?
Paid advertisements and organic search results are separate. Google states that it does not accept payment to crawl a website more frequently or rank a page higher in its organic results.
Key Conclusions
The most important points about how search engines work can be summarized as follows.
- Crawling, indexing, and ranking are separate processes that require separate diagnostic checks.
- A discovered or crawled page is not automatically added to a search engine’s index.
- An indexed page is eligible to appear but is not guaranteed a high position or visibility for every query.
- Internal links and a logical site structure help crawlers discover pages and understand their relationships.
- Ranking systems evaluate relevance, usefulness, meaning, and context using many signals rather than one simple formula.
- Search intent influences which page type and content format are most appropriate for a query.
- Official webmaster tools provide more useful diagnostic information than assumptions based only on manual searches.
Summary
Understanding crawling, indexing, and ranking makes SEO problems easier to diagnose. First determine whether the search engine knows the URL and can access it. Next check whether the page is eligible for indexing and whether the intended canonical version has been selected. Only after confirming these stages should you focus primarily on rankings, search intent, content usefulness, and competitive relevance.
For an online store, this knowledge helps distinguish a technical visibility issue from a content or targeting issue. The article Do I Need to Know SEO for My Online Store to Attract Customers from Google? provides additional context for store owners deciding how deeply they need to understand and manage SEO themselves.